Explore text at scale with PyPLN.
PyPLN was designed as a distributed platform for natural language processing, document analysis, full-text search and interactive visualizations.
An informational archive of the original project—not a currently hosted NLP service.
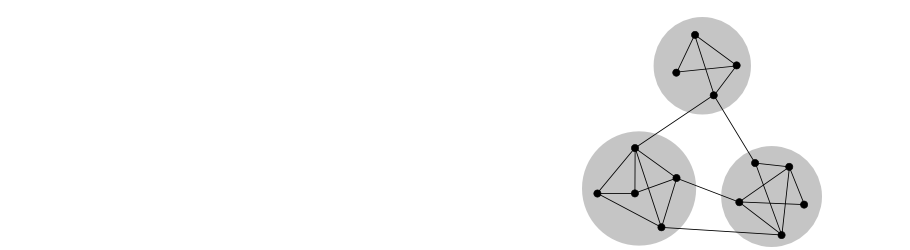 Distributed processing • Original archive graphic
From raw documents to meaningful insights
Explore four capabilities described in the original PyPLN website. Images are preserved from the archived project.
Distributed architecture
Designed to spread NLP and analytical tasks across available computing resources.
Learn more ↗
Document metadata
File-type and language detection to inform downstream text analysis workflows.
Learn more ↗
Full-text search
Search through documents and corpora using an integrated search capability.
Learn more ↗A research project built around text analysis
The archived PyPLN site describes a web-based platform for managing documents and corpora, extracting information, and visualizing linguistic analysis.
It was developed by the Núcleo de Análise e Modelagem de Dados research group at Fundação Getúlio Vargas in Rio de Janeiro, Brazil.
Organize text material for analysis and exploration.
Explore part-of-speech tags and word frequency statistics.
Use visual interfaces to examine analysis results.
Built with open-source tools
The original project listed these technologies. They are historical references, not a list of supported versions.
 Python
 Django
 Whoosh
 MongoDB
 ZeroMQ
 NLTK
Looking for PyPLN source code?
Explore the project repositories linked by the archived site.